
Label mapping (mapping.txt)#
Ethograph uses integer label IDs , e.g. in the TSV file (labels
column). The mapping.txt contains a mapping from these integers to the label names. This is the same format as used in the action-segmentation literature where models predict a per-frame class index and a dataset-level mapping.txt lists the corresponding action names.
One major benefit of this format is that if you rename a behaviour once in mapping.txt, it propagates everywhere (old backups, predictions, exports).
Format#
Whitespace-delimited, one label per line. The full schema is
<id> <name> [<branch>] [<event_type>] — both trailing fields are
optional with defaults (branch=0, event_type=state):
0 background
1 pullOutStick
2 diagonalToBox
3 toss 0
4 nod 1
5 reachLeftCorner 0
11 peck 0 point
12 call 1 point
Rules:
ID
0is alwaysbackground. It is excluded from display, export, and model loss.IDs don’t have to be contiguous, but they must be unique.
Names should be valid identifiers (no spaces) so they round-trip through Crowsetta text formats cleanly.
Trailing whitespace is ignored; blank lines are skipped.
branchis an optional integer grouping labels for independent labeling (see Label branches). Defaults to0.event_typeis"state"(interval, default) or"point"(instantaneous marker — see State vs point events below). Lines without it are treated as state events, so existing mapping files keep working unchanged.
To declare a point class without a custom branch you must still write the
default branch explicitly, because the columns are positional:
11 peck 0 point — not 11 peck point.
Where mapping.txt lives#
Define the label vocabulary once per research project: put mapping.txt at the
root of your project folder (chosen on the start page), and every session
you open uses it.
my_project/
    ├── mapping.txt                    # the project's label_id → name vocabulary
    ├── skeleton/                      # one YAML per skeleton
    ├── segment/segment.yaml           # action-segmentation config (copy from ~/.ethograph/defaults/)
    └── spot/spot.yaml                 # pixel event-spotting config
Tip
A local session_01/.ethograph/mapping.txt overrides the project’s copy for that
session (the GUI warns when they disagree). Without a project mapping.txt,
the default in ~/.ethograph/defaults/mapping.txt is used.
Editing it from the GUI#
Settings ▸ Create / edit label mapping.txt… opens the file in use as a table:
one row per label, with the ID read-only (it is the label’s identity in
labels.tsv — renaming a label keeps its rows, changing its ID would orphan
them), and the name, branch and event type editable. Add label takes the next
free ID; Open mapping.txt… loads a different file to edit.
With no mapping.txt yet, the table starts from ~/.ethograph/defaults/, and
saving writes the project’s own. Saving reloads the vocabulary everywhere at
once — the branch sections, the plots and the label table.
File ▸ Import labels only ever reads the mapping (and appends classes the imported file names, below); it is not a second place to define it.
Importing labels from other formats#
You can also import labels from Crowsetta or pynapple / NWB IntervalSet
files. These carry a label string (e.g. grasp) instead of Ethograph’s integer
ID. On import, names already in mapping.txt keep their ID; new names are
appended to the project’s mapping.txt with the next free ID, and the GUI says
which classes it added.
State vs point events#
Every label is one of two kinds:
Kind |
Stored as |
Use for |
|---|---|---|
|
interval ( |
Behaviours with a duration: walk, syllable |
|
instant ( |
Instantaneous events: peck, brief call |
The kind is declared per class in mapping.txt (4th column, see above) and
stored per row in the TSV (event_type column). When a class is declared
point in mapping.txt, the labelling shortcut drops a marker at the
playhead instead of starting an interval drag.
Point events pass through every interval operation (purge, stitch, snap, changepoint correction) untouched — they have no duration, so concepts like “too short” or “stitch the gap” don’t apply to them.
Reading it programmatically#
load_mapping() gives the two lookups:
from ethograph.labels.intervals import load_mapping

class_to_idx, idx_to_class = load_mapping("mapping.txt")
class_to_idx["pullOutStick"]  # 1
idx_to_class[1]  # "pullOutStick"
For plotting, load_label_mapping() returns
one dict per label with a colour assigned, and
plot_label_segments() shades every interval of a
labels DataFrame with that colour. The example below opens one trial of the
Moll2025 example session and draws its labels over the beak-tip speed:
import matplotlib.patches as mpatches
import matplotlib.pyplot as plt

import ethograph as eto
from ethograph.datasets import dataset_dir
from ethograph.io.session_layout import labels_path
from ethograph.labels.intervals import load_label_mapping
from ethograph.labels.plots import plot_label_segments
from ethograph.labels.tsv_store import load_labels_tsv

session = dataset_dir("moll2025")  # the downloaded example session folder
dt = eto.open(session / "Trial_data.nc")
ds = dt.trial(41)

mappings = load_label_mapping(session / ".ethograph" / "mapping.txt")
labels = load_labels_tsv(labels_path(session))  # the session's labels.tsv
labels = labels[labels["trial"] == 41]

speed = ds["speed"].sel(keypoint="beakTip", individual="Crow1")
fig, ax = plt.subplots(figsize=(9, 3.6))
ax.plot(speed["time"], speed, color="black", lw=0.8)
plot_label_segments(ax, labels, mappings, individual="Crow1", alpha=0.4)

used = sorted(labels["labels"].unique())
ax.legend(
    handles=[mpatches.Patch(color=mappings[i]["color"], label=mappings[i]["name"]) for i in used],
    loc="upper center", bbox_to_anchor=(0.5, -0.28), ncol=7, fontsize=7, frameon=False,
)
ax.set_xlabel("time (s)")
ax.set_ylabel("beakTip speed")
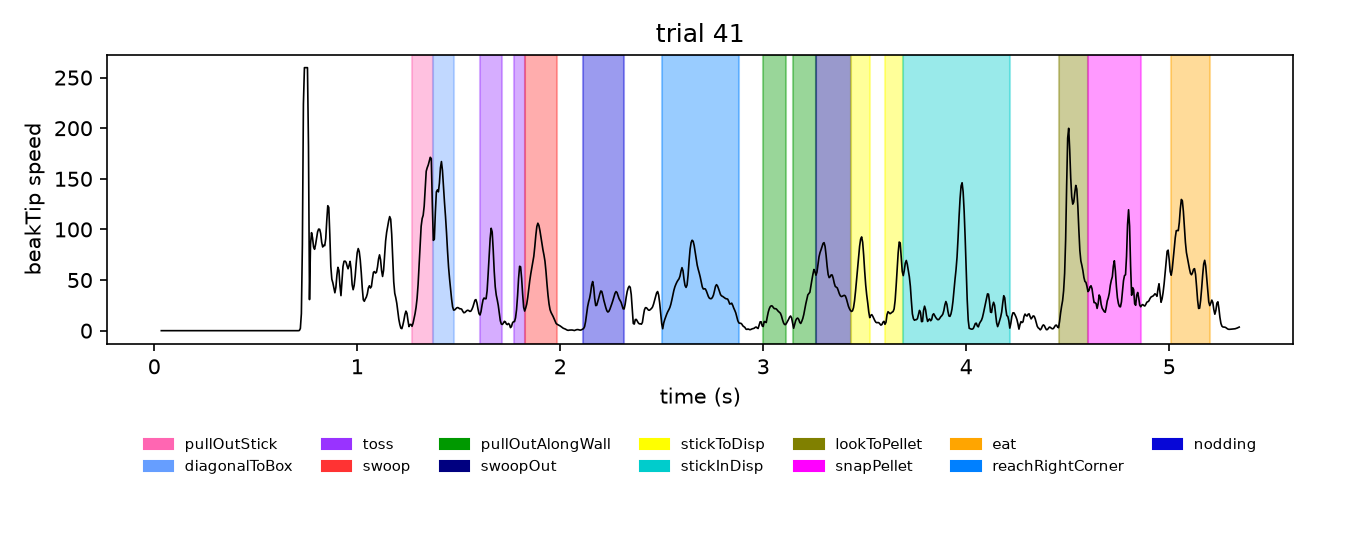
labels is the TSV as a DataFrame with onset_s, offset_s, labels,
individual and trial columns, so filtering it by trial or individual is
ordinary pandas.